Project contents
Data
Where the Action Actually Happens at F1 GPs
Corner-by-corner race data, so a ticket buys you something worth watching
- Astro
- TypeScript
- Python
- pandas
- SQLite
- Cloudflare Pages
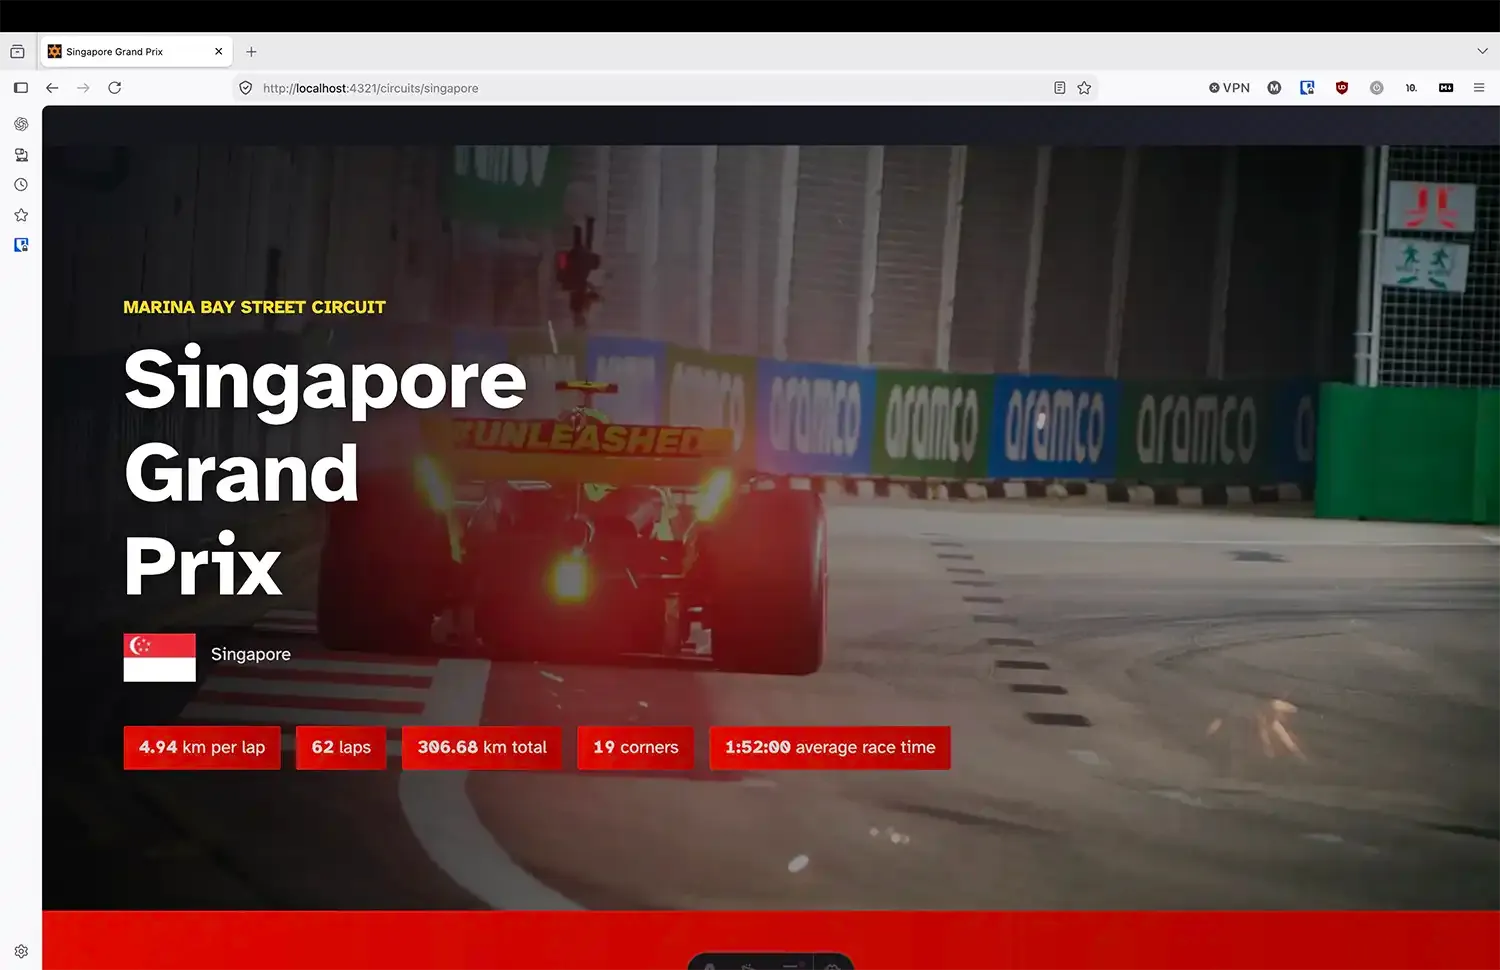
I’ve been a lifelong Formula 1 fan and I finally got to got to a race for the first time at the 2018 Japanese Grand Prix at Suzuka. I then went to the 2019 and 2023 Singapore races. The first two were great, plenty of action and overtakes from where I was sitting, While I had a great time at the third, most people who watched the 2023 Singapore Grand Prix wouldn’t say it was brimming with action and overtakes. That’s actually where the idea for this project started.
Tickets for F1 races are expensive, so in the future I wanted to know roughly how much action I would probably get to see at a particular race and grandstand. While you get a rough idea of what is better based on price (the more expensive, generally the better the viewing experience), it’s hard to pick a ticket.
Additionally, I was interested to see how the action at each section played out over the race. For example, is it better paying double or triple for turn 1 just to see choas on lap 1, or is it better to go with a cheaper corner further along the track that has action more spread out over the race.
This site is my attempt at answering that problem. Every corner and straight at a circuit is broken down by what has actually happened there. This includes overtakes, close battles, crashes, the laps they tend to happen on and which grandstands can see them.
The original idea seemed fairly simple, but it actually has turned into quite a complex project. For example, I found that a lot of overtakes at Turn 7 in Singapore happen before the apex of the corner. This means that unless you are on the left of the Stanford grandstand, you won’t get a view of them.
Where it is right now
The main data pipeline is set up and I am just working on getting data on more races.
Working now
- Two circuit guides, 29 grandstand pages and a global rankings leaderboard
- The full database loader, including catalogue validation and traceability back to every source row
- Global rankings generated entirely from SQL and checked field by field against the old output
validate_db.py, which checks 525 keys covering per-section counts, zone counts and summary counts
Planned
- Adding a third circuit, which will be the first proper test of all the things a two-circuit dataset cannot reveal
- Adding more race years for each circuit, which is more of a data-gathering problem than a programming one
Updates
Recent progress
Updates are bullet-point summaries generated with AI from my commits and build notes, then checked by me. Project articles and learning notes are written by me.
-
- The one-year circuit can’t fail a denominator test, since dividing by one changes nothing. Only the three-year circuit now counts as evidence for averaging checks.
- Replaced the comparison script. It never compared
race_phases, sorted lists the code deliberately orders, and keyed grandstands by the non-unique code. The new one compares every field and requires accepted differences to be declared. - Froze the old pipeline’s output in
baseline/, pinned to a commit, so validation doesn’t end up comparing the database with itself after cutover. Widened validation from 195 to 525 keys and confirmed the checks can fail. - Resolved a suspected unzoned incident (zones 7/7/7 against a total of 8). The zones overlap, so nothing was wrong.
- Added a
source_incidentstable: the circuit summary counts spreadsheet rows, not row and section pairs, and one 2023 row with no section could not be recovered fromincidents. - See Five verification failures.
-
- Rewrote the global rankings as three SQL queries plus a Python pass. 31 corners and 14 straights matched the old output exactly. The only grandstand differences were nine floating point artefacts the old code had been shipping, such as
14.399999999999999. ORDER BY g.grandstand_id, gv.rowidreproduced the old list ordering with zero differences across 29 grandstands.- Grandstand lookups were keyed by
code, which is only unique per circuit. Forcing a collision merged two grandstands (28 instead of 29). Now keyed bygrandstand_id, changed in a single commit, because the halfway state deleted a grandstand instead. - The circuit page, still on the old pipeline, listed two spreadsheet typos as straights that the new rankings page correctly dropped. Fixed the typos in the source workbook rather than rushing the migration.
- Those typos were cells showing
9-10that held dates under ad\-mnumber format. Set them to strings with Text format; database validation went to 0 mismatches. - See Migrating by predicted diffs.
- Rewrote the global rankings as three SQL queries plus a Python pass. 31 corners and 14 straights matched the old output exactly. The only grandstand differences were nine floating point artefacts the old code had been shipping, such as
-
- First run of the SQL loader: four transcription errors that each failed loudly, and one that didn’t. The incident insert sat inside a loop that skips crash sheets, so
is_crashwas false for every row while the load reported success. Split the loader into two passes.
- First run of the SQL loader: four transcription errors that each failed loudly, and one that didn’t. The incident insert sat inside a loop that skips crash sheets, so