Project contents
AI
Automating Garage Dreams
Turning an old car site into one that writes itself
- Astro
- TypeScript
- Cloudflare Pages
- Raspberry Pi
- Gemma
- Claude
- Codex
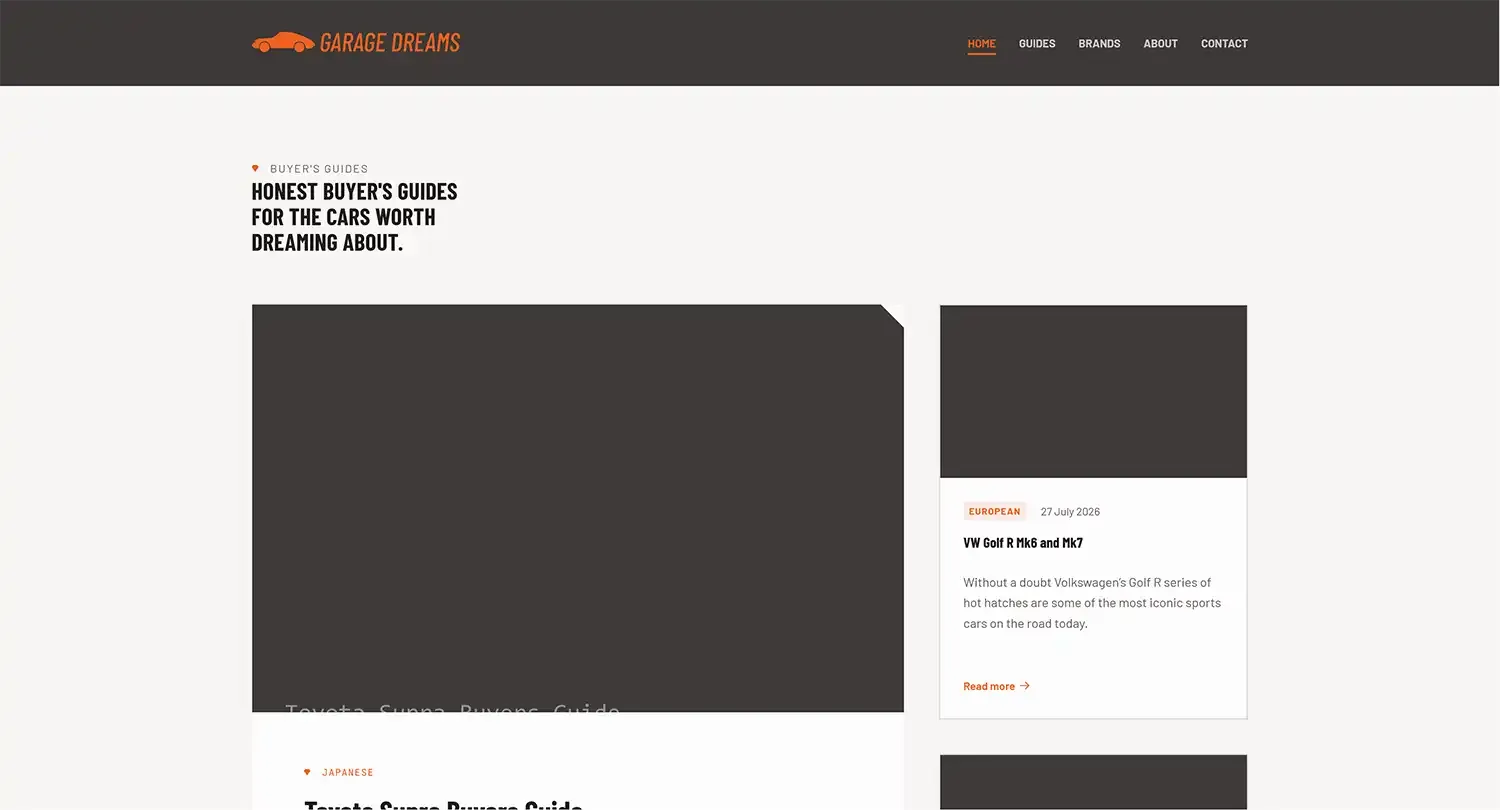
Garage Dreams was an automotive site I built and ran from 2016 until around 2024. Its buyer’s guides ran to 20,000, 30,000 and sometimes 40,000 words, and were created by going through every forum, publication and video I could find. At its peak the site was doing 2,000 to 3,000 active users a day and had become a sizeable share of my earnings.
However, after a number of Google Updates (most notable around the time when AI really took off), the site’s rankings and traffic were massively impacted. After fighting it for a while, I decided to pull the plug on the site as while I enjoyed writing about motoring topics and buyer’s guides, I needed to focus my efforts elsewhere.
The site and content laid dormant until I decided I could bring it back as an AI automation project. Yes, it wouldn’t be the same, but I was interested to see how well I could get this working. In fact, for some reason I even wanted to see if I could do this with just a local language model, a Raspberry Pi 5 8gb, Cloudflare pages and a solar panel for power. Essentially creating a fully autonomous, free to run website (well, except for the domain name). In the end, the solar panel idea didn’t make it but I may have a go at some point.
Why use my old Content
The biggest problem I find with AI generated content sites is that they are usually just getting Chat GPT, Claude or whatever AI tool to write off the cuff. The benefit I had with Garage Dreams is that I knew the content was correct as I had spent hours trowling through forums and specifications for each guide and article. I also don’t think the local model would have survived without using pre-written content. While the focus isn’t really on the articles themselves, but more the process, I still wanted them to be correct and I don’t think a small model running off an 8gb Raspberry Pi would have been up to the task.
What is the site built on?
The original WordPress site was built around a custom WordPress template with classifieds listings, guides and general articles. I threw all that away and rebuilt the site using the Astro framework. I build most of my sites around Astro (and Directus for a CMS) these days as I find they perform way better, are more secure, and I don’t have to worry about pesky plugin or core updates. Basically, the sites can be left without management, which makes it perfect for an automated blog.
Where it is at right now
The whole setup is basically done and automated. I did start with setting the articles to “draft” to check that the process works, but now the articles and images publish directly to the live site and I can review if necessary.
Working now
- The full drafting, linting, dual review, build and commit path, running end to end
- Selection of the old guides migrated onto the new Astro site
- Corpus auditing, run logging, and a report that turns a batch of runs into numbers
- 295 tests, including four real Astro builds
- Automated codex image cover generation
Future Plans
- Longer guides, generated by a frontier model and cross-reviewed
Updates
Recent progress
Updates are bullet-point summaries generated with AI from my commits and build notes, then checked by me. Project articles and learning notes are written by me.
-
- The monitor reported five green checks (26 records, newest run 23.2 hours old, last run published, in sync with the remote) and all three of those facts were wrong. The remote held 27 records, the newest was eight hours old, and it had skipped. Two defects compounded: the upstream check measured only whether the branch was ahead, so a purely behind checkout scored zero and printed “in sync”; and the record checks read the local working tree, which
--fetchdoes not update. On the publishing host the tree and the remote coincide, so the machine the monitor was designed for is the one machine where the bug is invisible. - Nine burn-in drafts reviewed against their sources: three carried article-introduced faults, and all three had passed both reviewers. Each is the same shape: a fact kept and the qualifier that made it true discarded. One asserted a platform lineage the source paragraph exists to deny; one dropped “non verified test” from a top-speed figure; one rendered the end of Japan’s 280 PS advertising cap as a claim about the car’s power, beside a 308 PS figure.
- That retracts an earlier conclusion. “Both reviewers reliably catch dropped qualifiers” was drawn from two runs in which they did, which is a definition rather than a sample: a run they catch gets revised into the record, a run they miss publishes silently. The observed miss rate is three in nine and that is a floor, not an estimate. It matters most at the next stage, when the draft step disappears and the reviewers become the only check.
- Two further faults were source defects copied faithfully: a guide calling cast-iron brake discs carbon, and another calling a three-door hatchback a four-door. The pipeline behaved correctly in both cases, which is its own kind of finding.
- The sync damage recurred at four times the size: eight tracked files deleted with
(1)twins, including four published articles. The first method used to verify them reported all eight as differing, which would have meant eight files of real work to reconcile by hand. The method was wrong. Dumping a blob through a PowerShell redirect re-encodes it, so the comparison measures the shell rather than the files. Comparing object IDs the way git itself would showed all eight identical. Note the direction of that error: the broken method produced the alarming answer, and nobody double-checks bad news. - Added commands to move generated articles between draft and live in both directions, sharing one transaction that validates everything, holds the originals in memory and rolls back by exact path. It exists because after the draft stage is removed there is otherwise no route back for prose. The flip and its rollback do not differ by direction, so one function takes the source and target values and the round trip to the original bytes is asserted. There is deliberately no bulk form on the withdraw side.
- All nine drafts are now live, published in one commit by the command rather than by hand.
- The monitor reported five green checks (26 records, newest run 23.2 hours old, last run published, in sync with the remote) and all three of those facts were wrong. The remote held 27 records, the newest was eight hours old, and it had skipped. Two defects compounded: the upstream check measured only whether the branch was ahead, so a purely behind checkout scored zero and printed “in sync”; and the record checks read the local working tree, which
-
- An unattended cover run failed its own integrity check and left nothing behind to diagnose it with: no candidate, no session record. Rendering the prompt locally and hashing variants identified it exactly: the attested digest is
sha256(prompt + "\n"). That is the signature of hashing an echoed string in a shell. Switching the attestation from text to a digest a fortnight ago closed the Unicode serialisation boundary and not the shell’s trailing newline. - Ben’s call was to accept exactly one appended newline and nothing else. A second newline, a CRLF, a leading newline, a trailing space and a single dropped character all still fail, and both directions were mutation-checked.
- The retry selected a different article, because the failed one was deprioritised by its own recorded failure, and it passed.
- Second instance of the development-years fault: a cover for “The Development of the Mazda RX-8” asked for 2001-2003 for a car sold from 2003. Both instances are articles whose titles start “The Evolution of” or “The Development of”, which is a pattern rather than a coincidence. The images were correct both times.
- A 23-minute article run outlived the 15-minute sudo credential, so the job queued behind it sat waiting for a human. Worth knowing before anything depends on two long steps in sequence.
- An unattended cover run failed its own integrity check and left nothing behind to diagnose it with: no candidate, no session record. Rendering the prompt locally and hashing variants identified it exactly: the attested digest is
-
- The first draft run under systemd failed on a revision call that hit the token cap after 859 visible characters, and the cause is that the model thinks. The server streams reasoning on a separate field, the pipeline discards it, and it still spends the cap and the wall clock. A probe measured 400 tokens and 103 seconds of pure reasoning with no content at all; with thinking disabled the same call took 34 tokens and 8.4 seconds. Ben chose to keep thinking on and raise the cap to 4096, so a truncation message now reports the reasoning characters too.
- Covers became an unattended nightly job: select one missing article, generate, accept, apply, build, commit, push. A push adding a cover record opens a GitHub issue mentioning Ben, delivered by email and confirmed working, and a phone-triggered workflow reverts it. Every side effect is injected in tests, and three of the guards were mutated and watched failing.
- A failed cover run leaves no committed record, so the batch itself carries the state file, so a run killed mid-flight stays marked
startedand counts as a failure. Three failures on one article excludes it from selection rather than letting it burn a generation every night. - Checking the Pi for a leaked API key with
env | grepthrough sudo reported a match that was not there: sudo sets a variable containing the full command line, so grep matched its own text. - The alert path fired correctly and printed “(journal unavailable)”, because the handler unit could not read the journal it was reporting on. The failure path works; the part that tells you what failed did not.
- The first Pi cover recorded model years of 2008-2012 for a car that went on sale in mid-2012. The derivation takes the dominant cluster of years in the article body, and a development history names the announcement, the prototype and the launch, so the cluster is the development period, not the production run. The image came back correct anyway. Left alone deliberately: changing the derivation mid burn-in would muddy the tally it is being measured by.